Sixteen local models on one 24 GB GPU against six cloud settings. Eight coding tasks designed by
Claude Opus 5.5, graded by code, three runs each, plus two inference engines, a 256K long-context stress test and
a multi-user test.
Best cloud
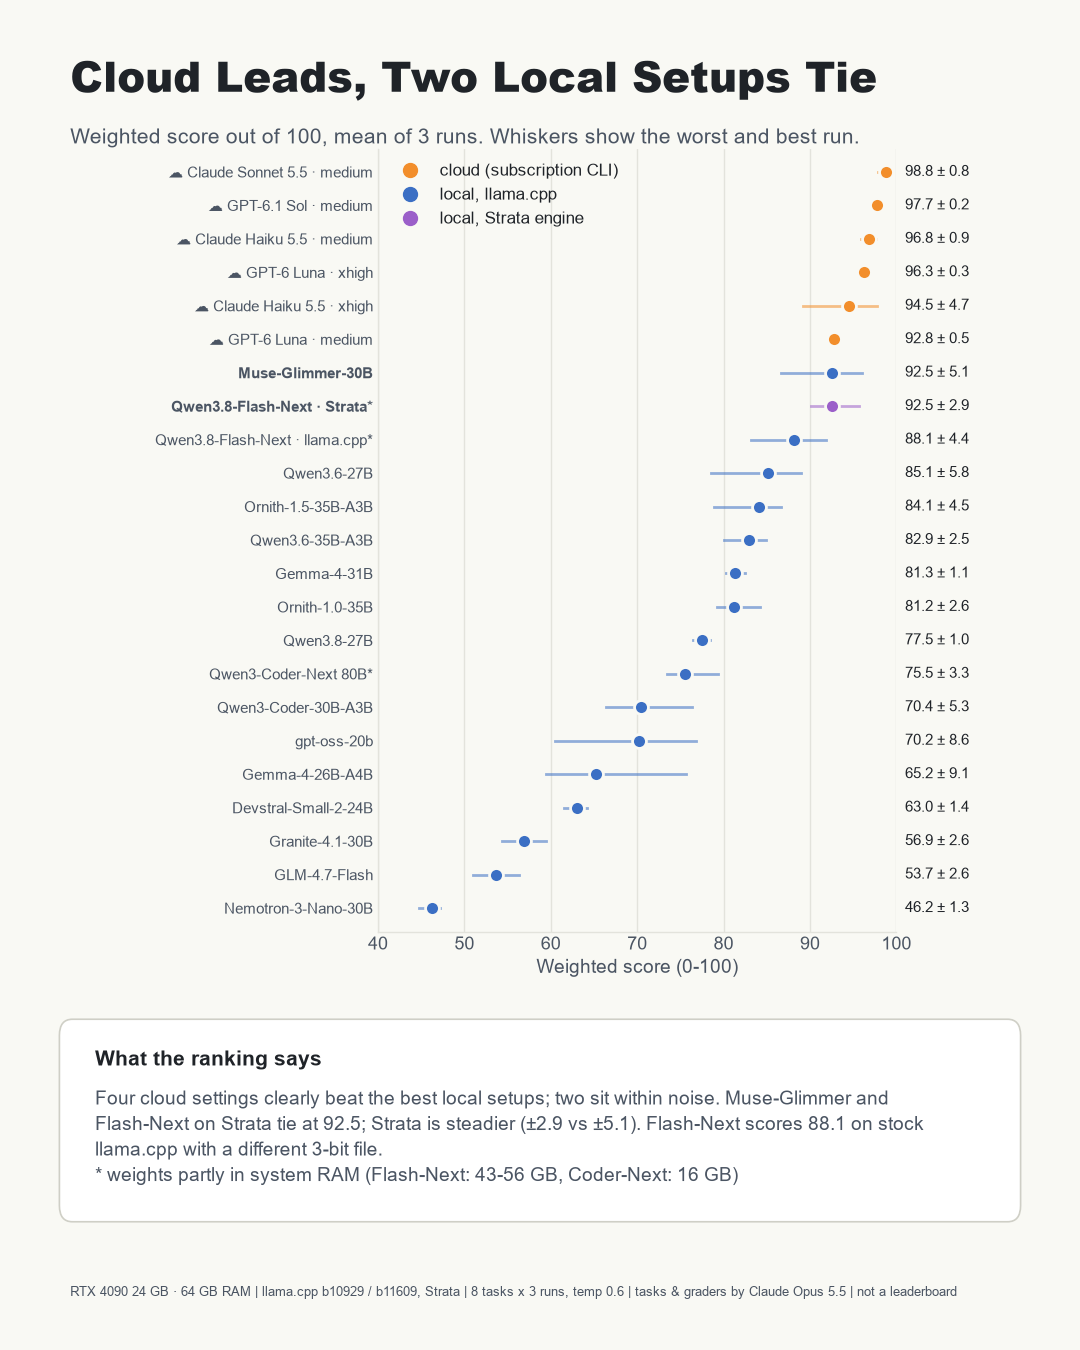
98.8
Claude Sonnet 5.5 · medium
Best local (tie)
92.5
Muse-Glimmer-30B · Qwen3.8-Flash-Next on Strata
Same model, other engine
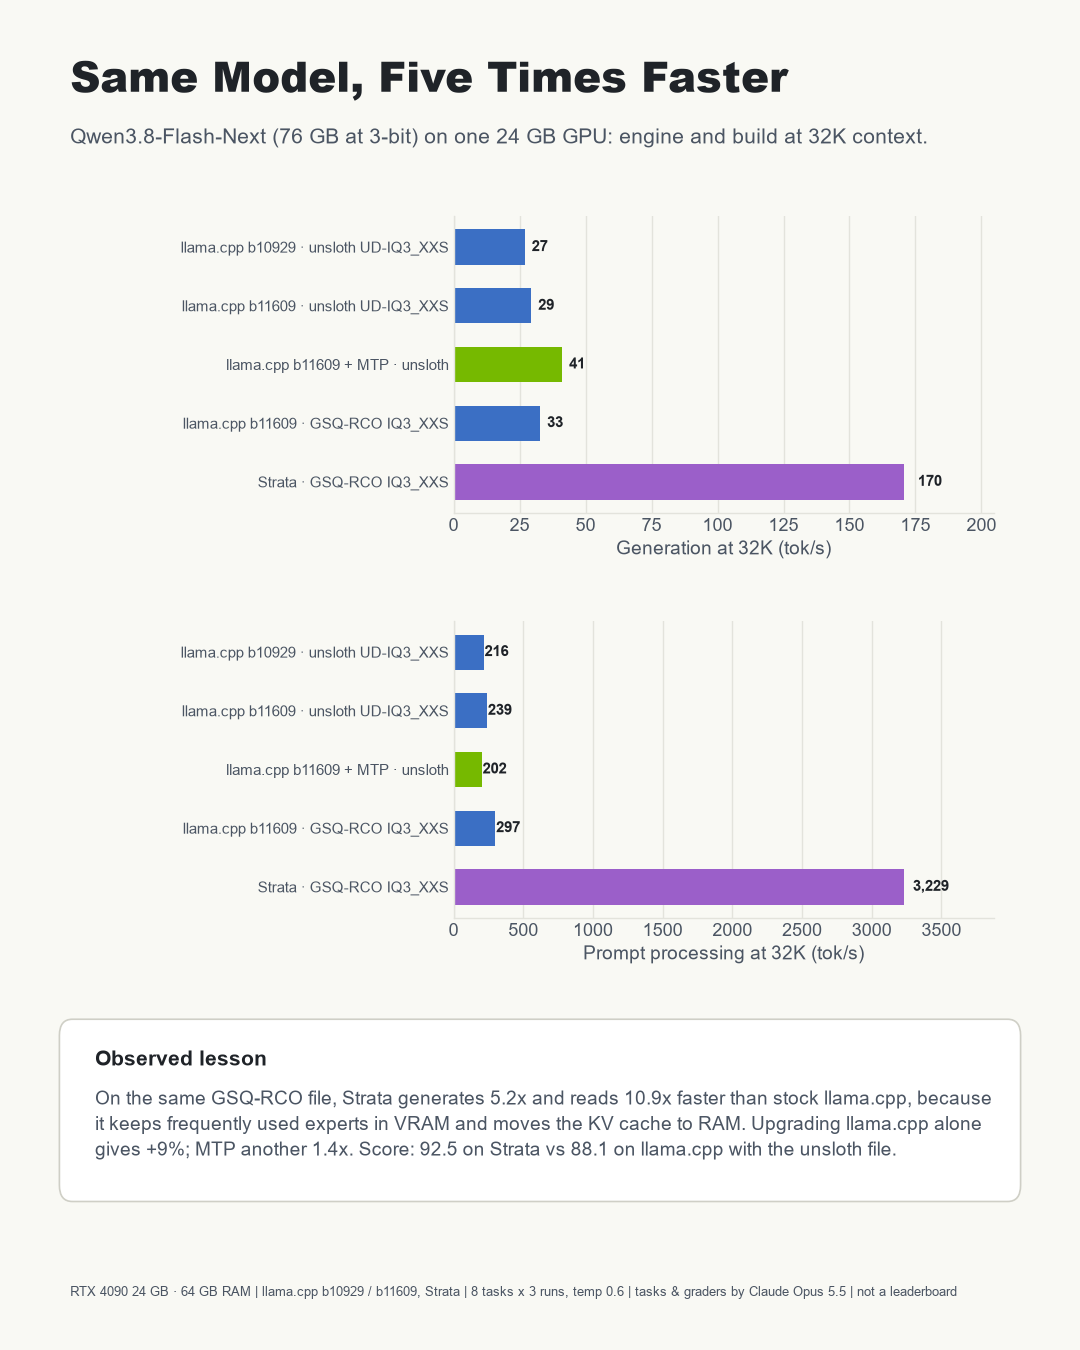
27 → 170
tok/s, llama.cpp vs Strata
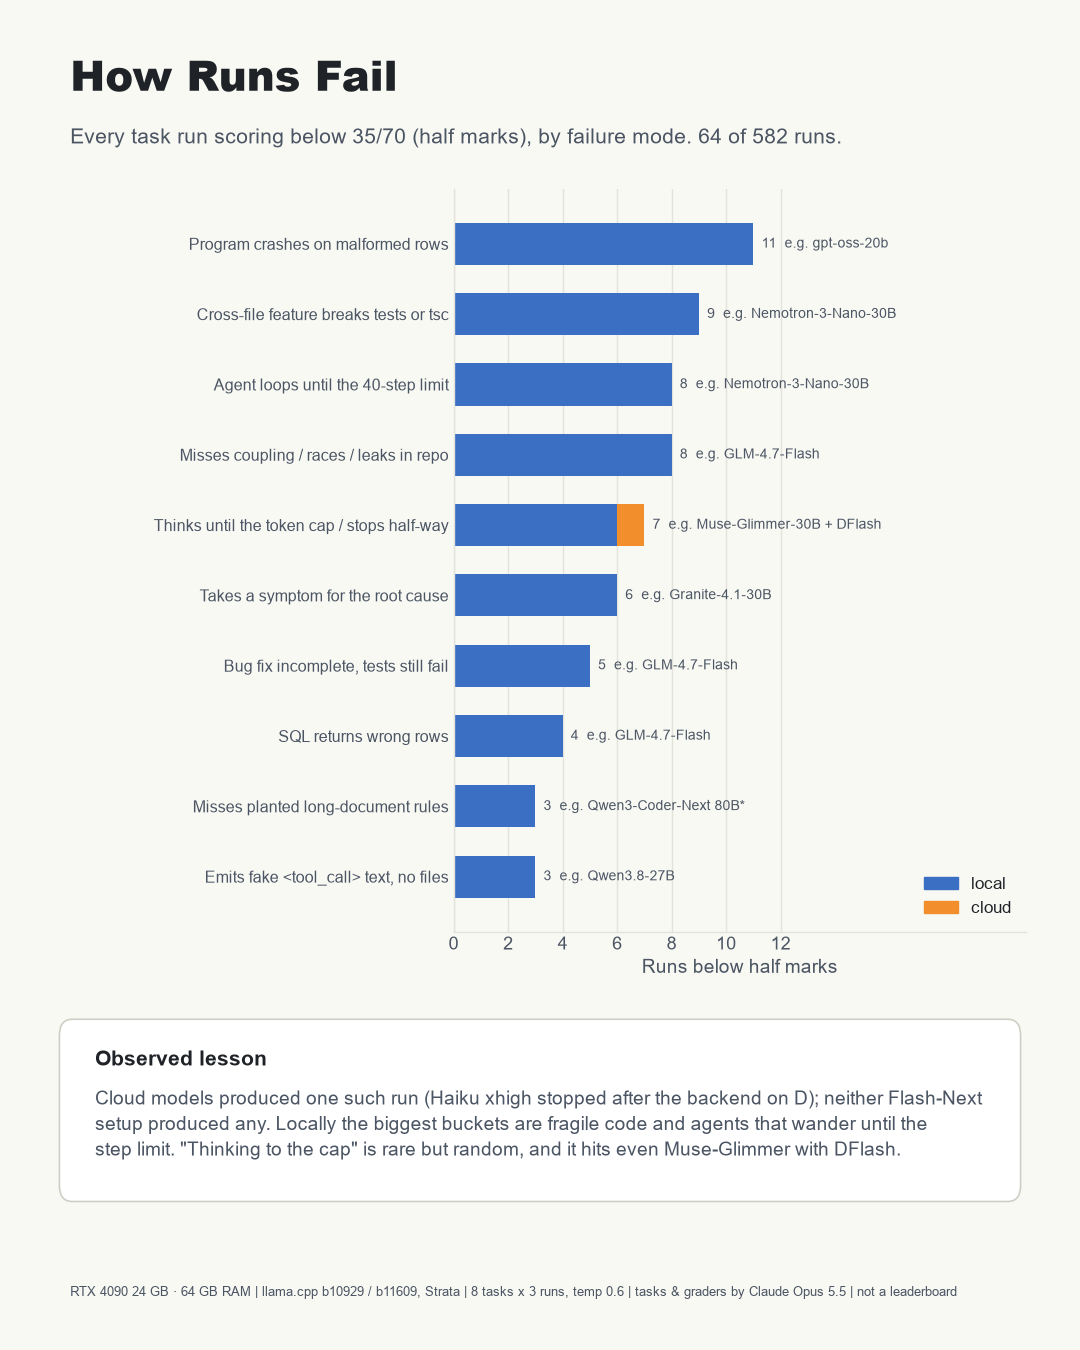
Runs below half marks
64 / 582
only 1 from the cloud
The test
One factory energy (MES) domain. Hidden tests and executed queries decide correctness;
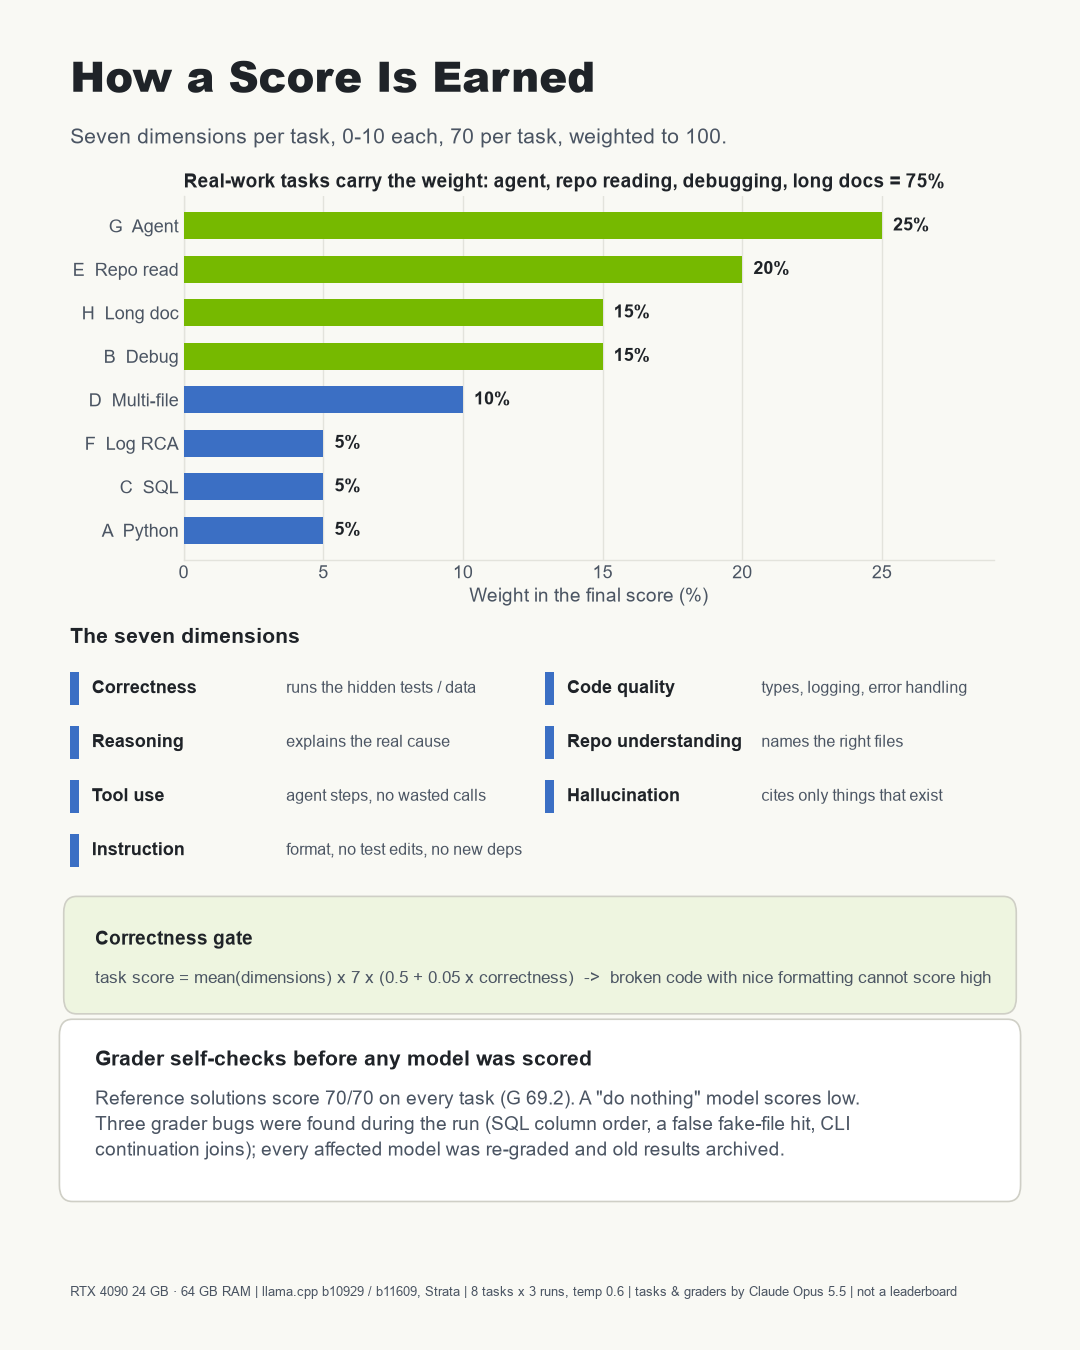
a correctness gate stops polished but broken answers from scoring high.
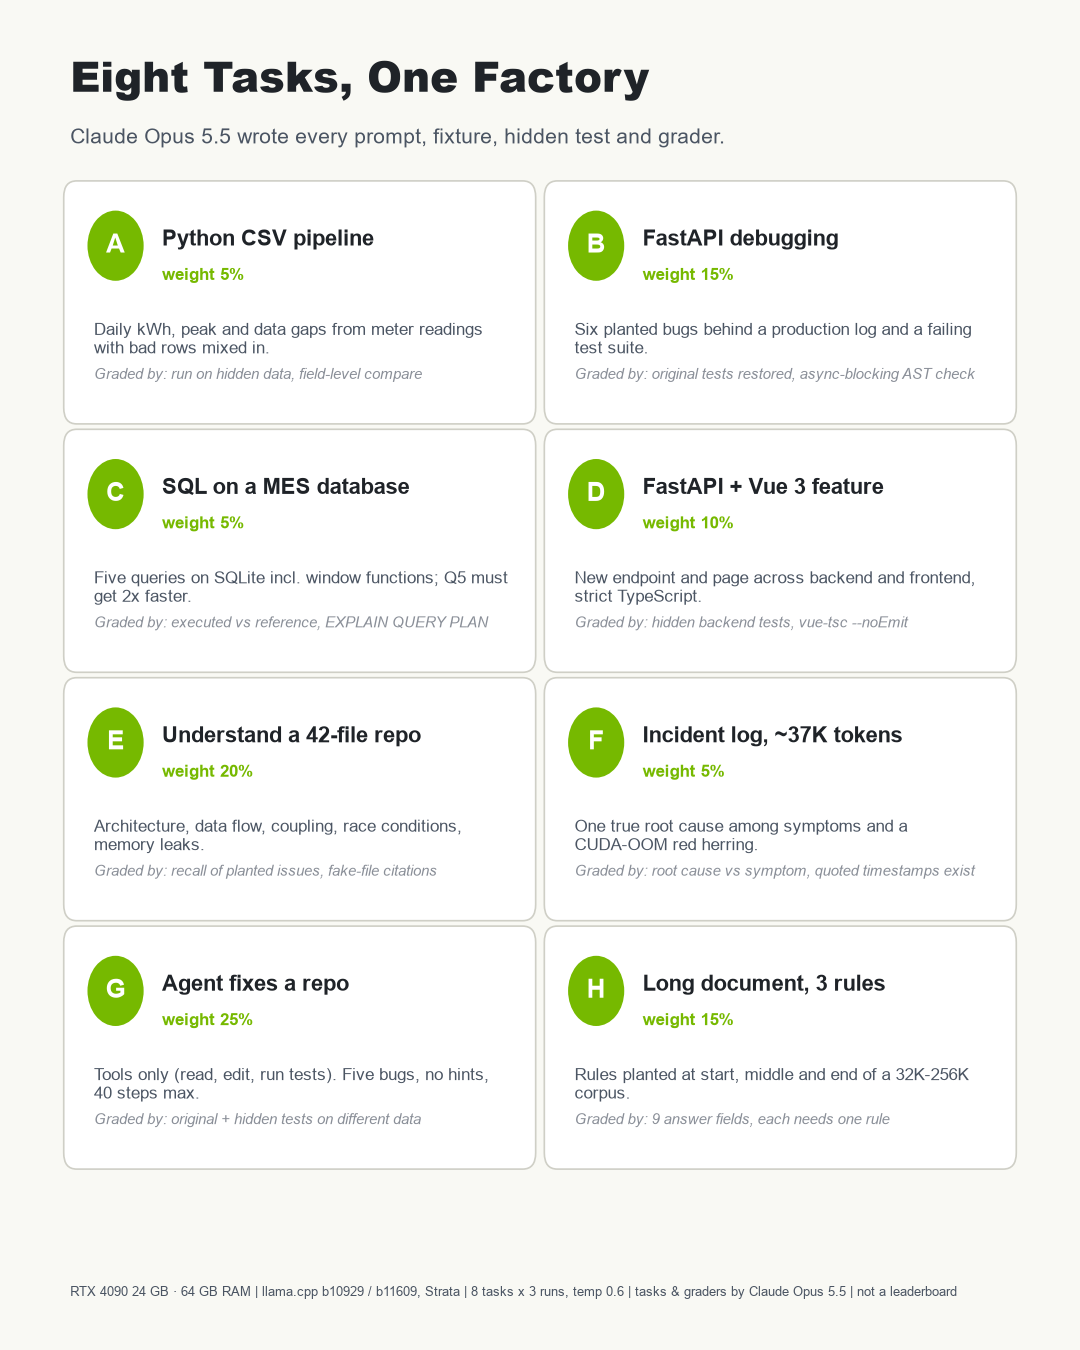
Eight tasks. Python, debugging, SQL, multi-file, repo reading, log root cause, agent, long document.Scoring. Seven dimensions, weighted to 100, graders validated against reference solutions.
Results
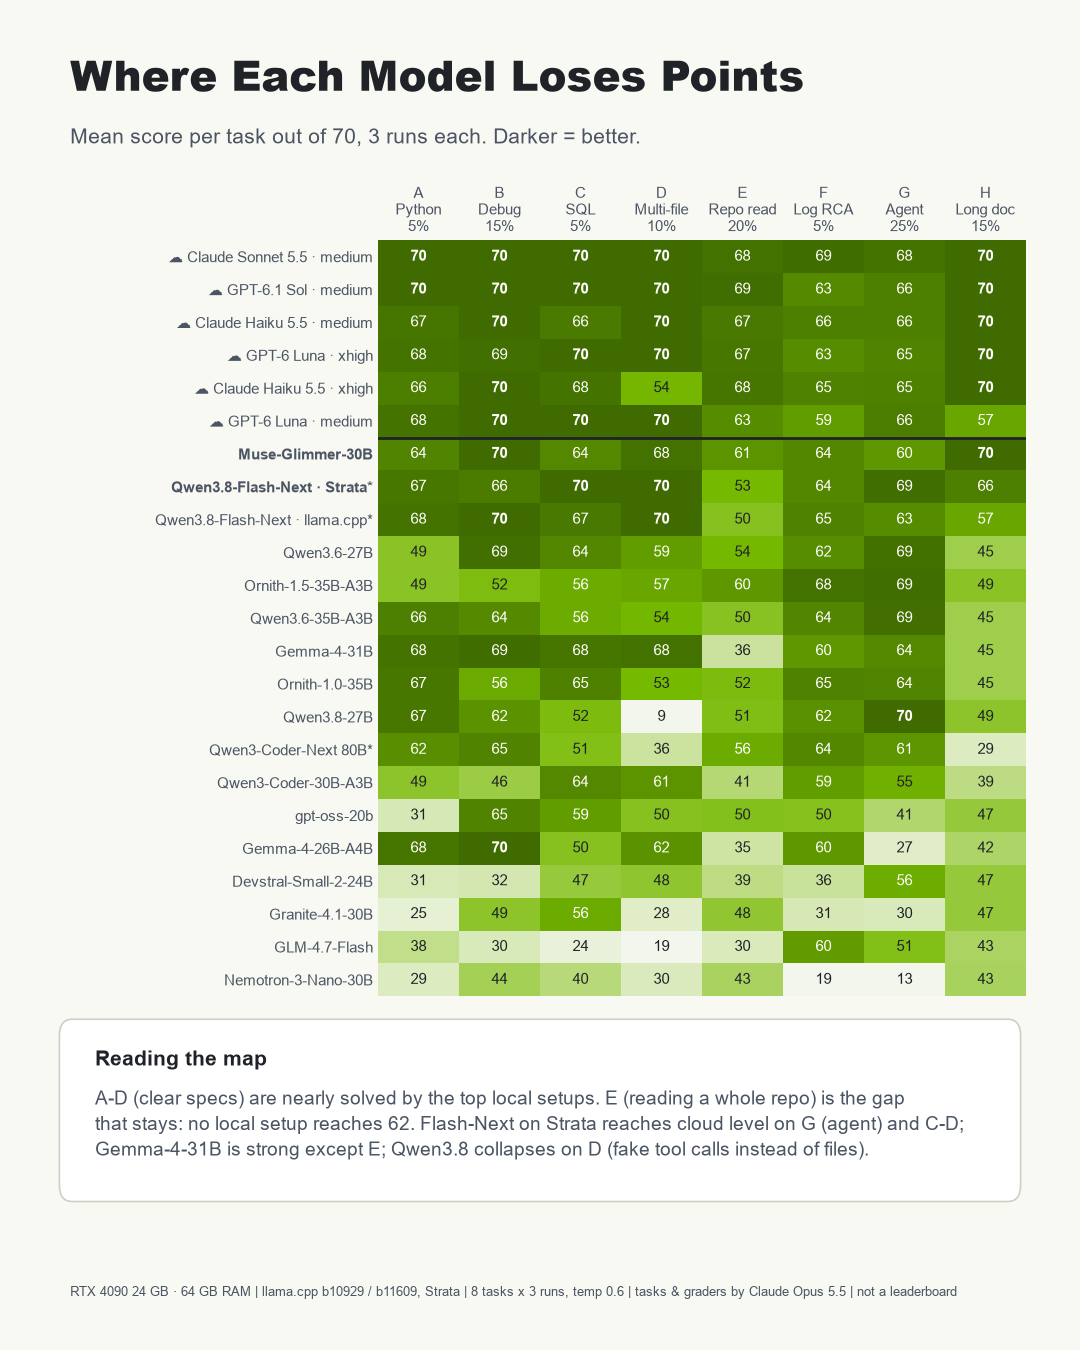
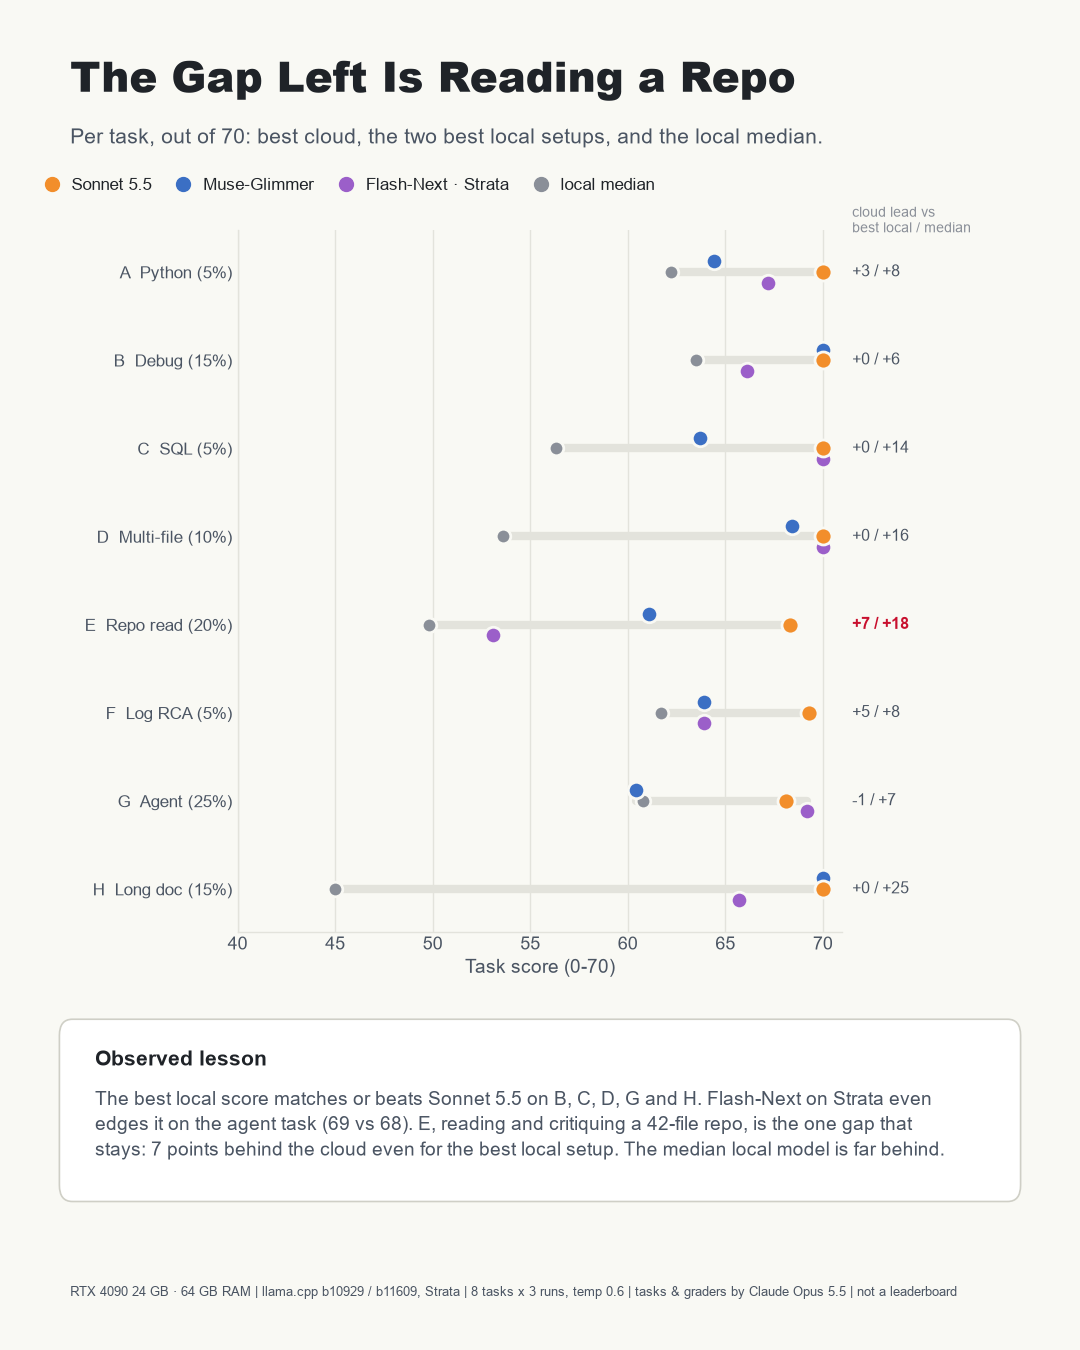
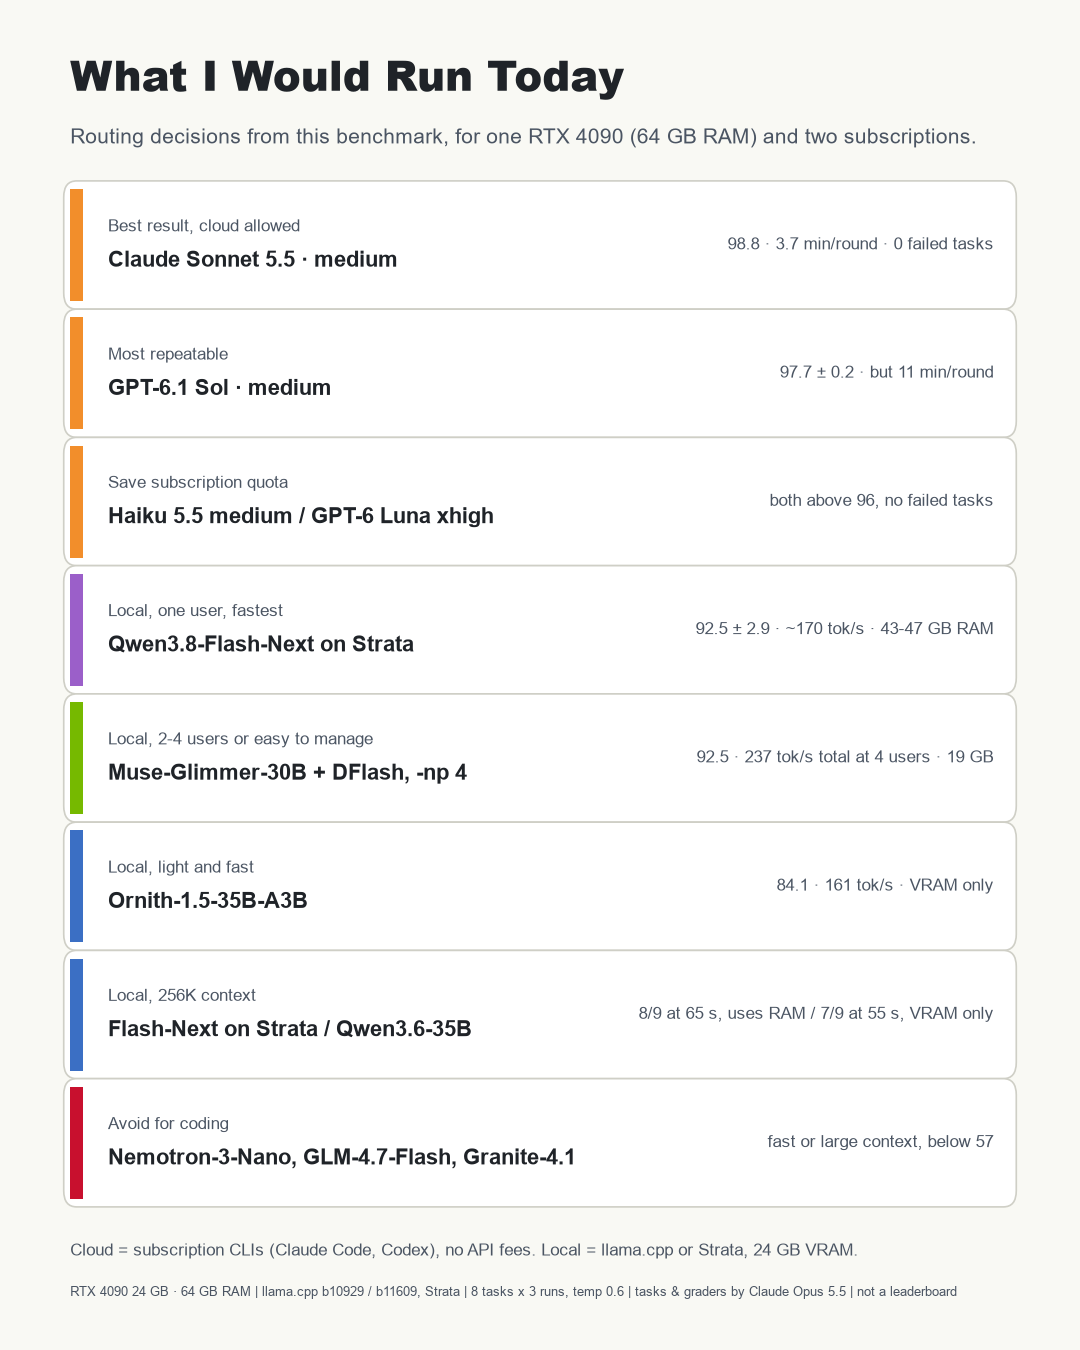
Ranking. Cloud leads; two local setups tie at 92.5.Per task. Clear-spec tasks are nearly solved locally.The gap. Only repo reading (E) stays clearly behind.Routing. What to run for each need.
Error analysis
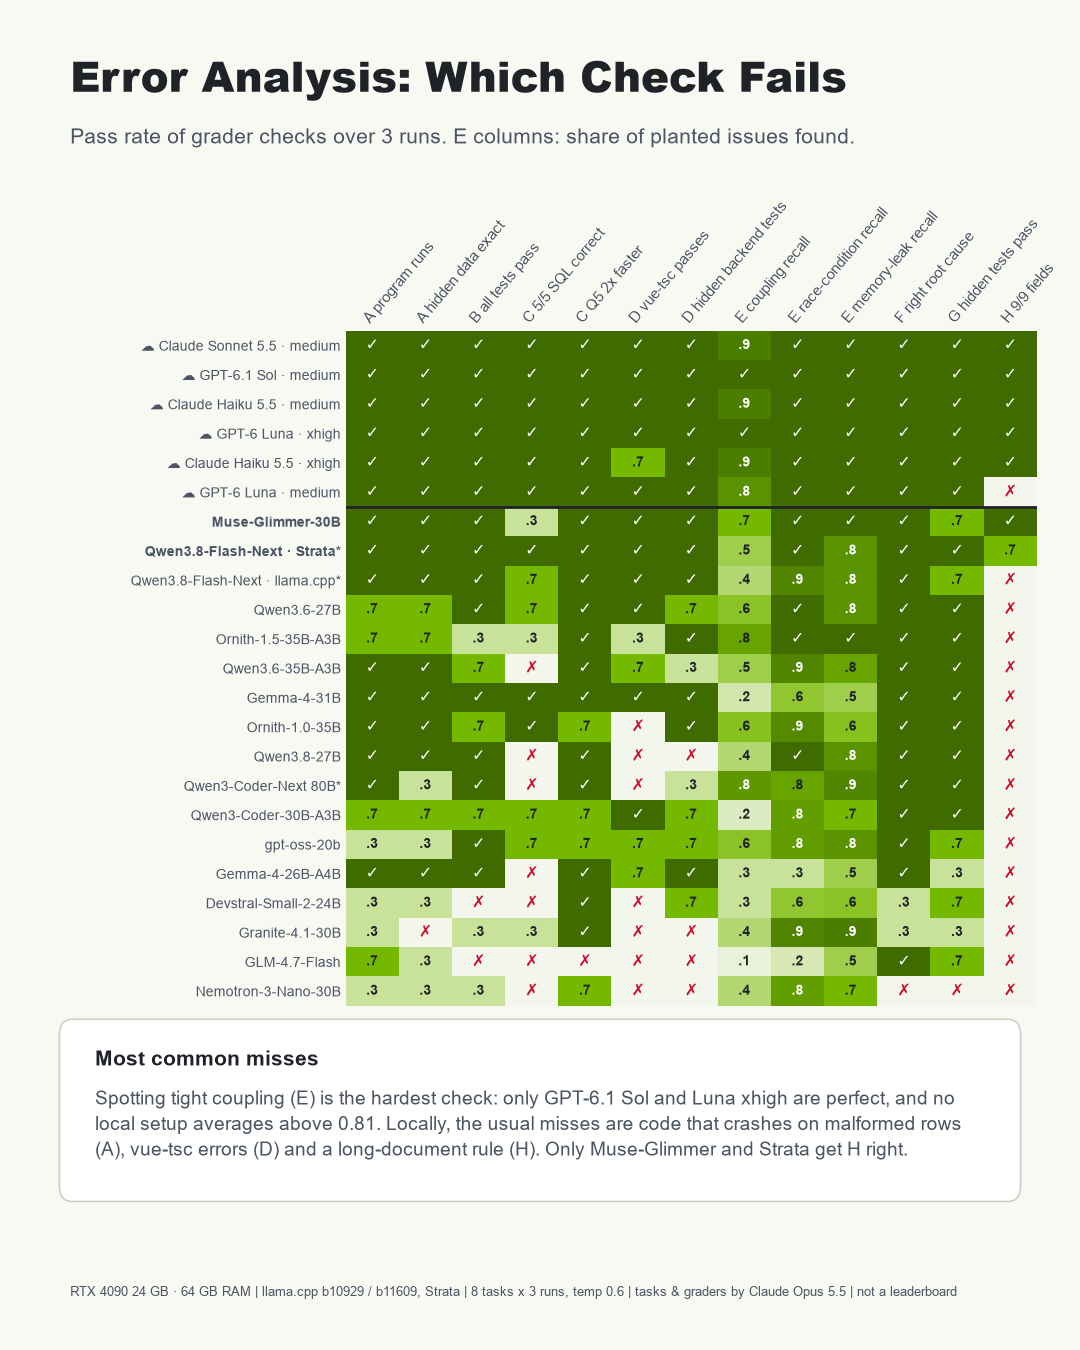
Which check fails. Tight coupling is the hardest check for everyone.How runs fail. Fragile code, looping agents, thinking to the cap.
Efficiency
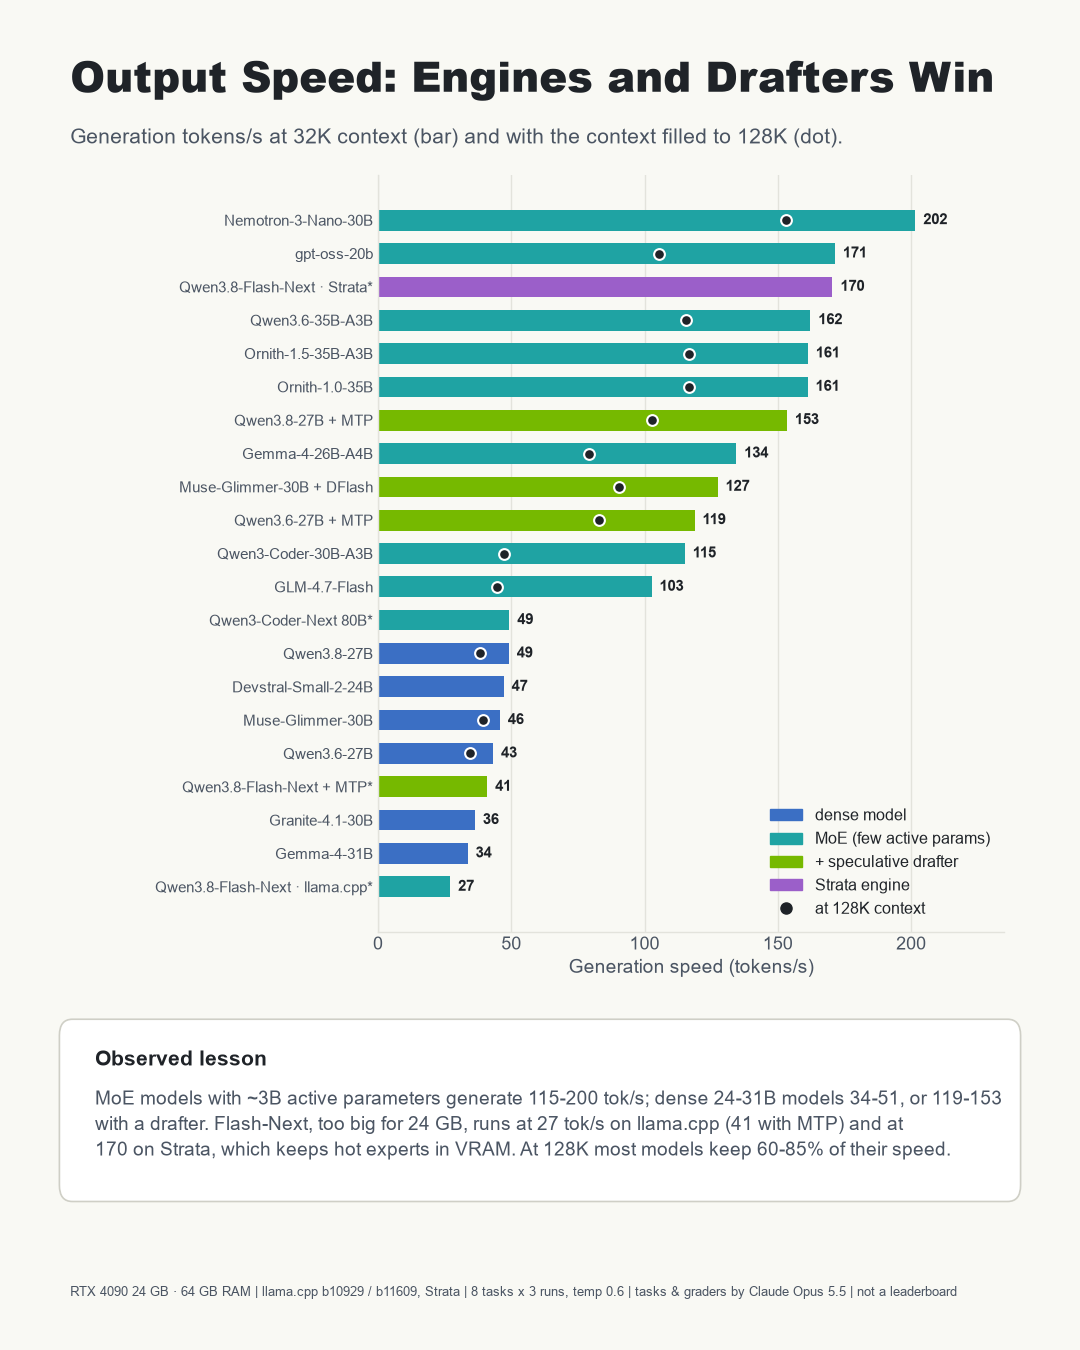
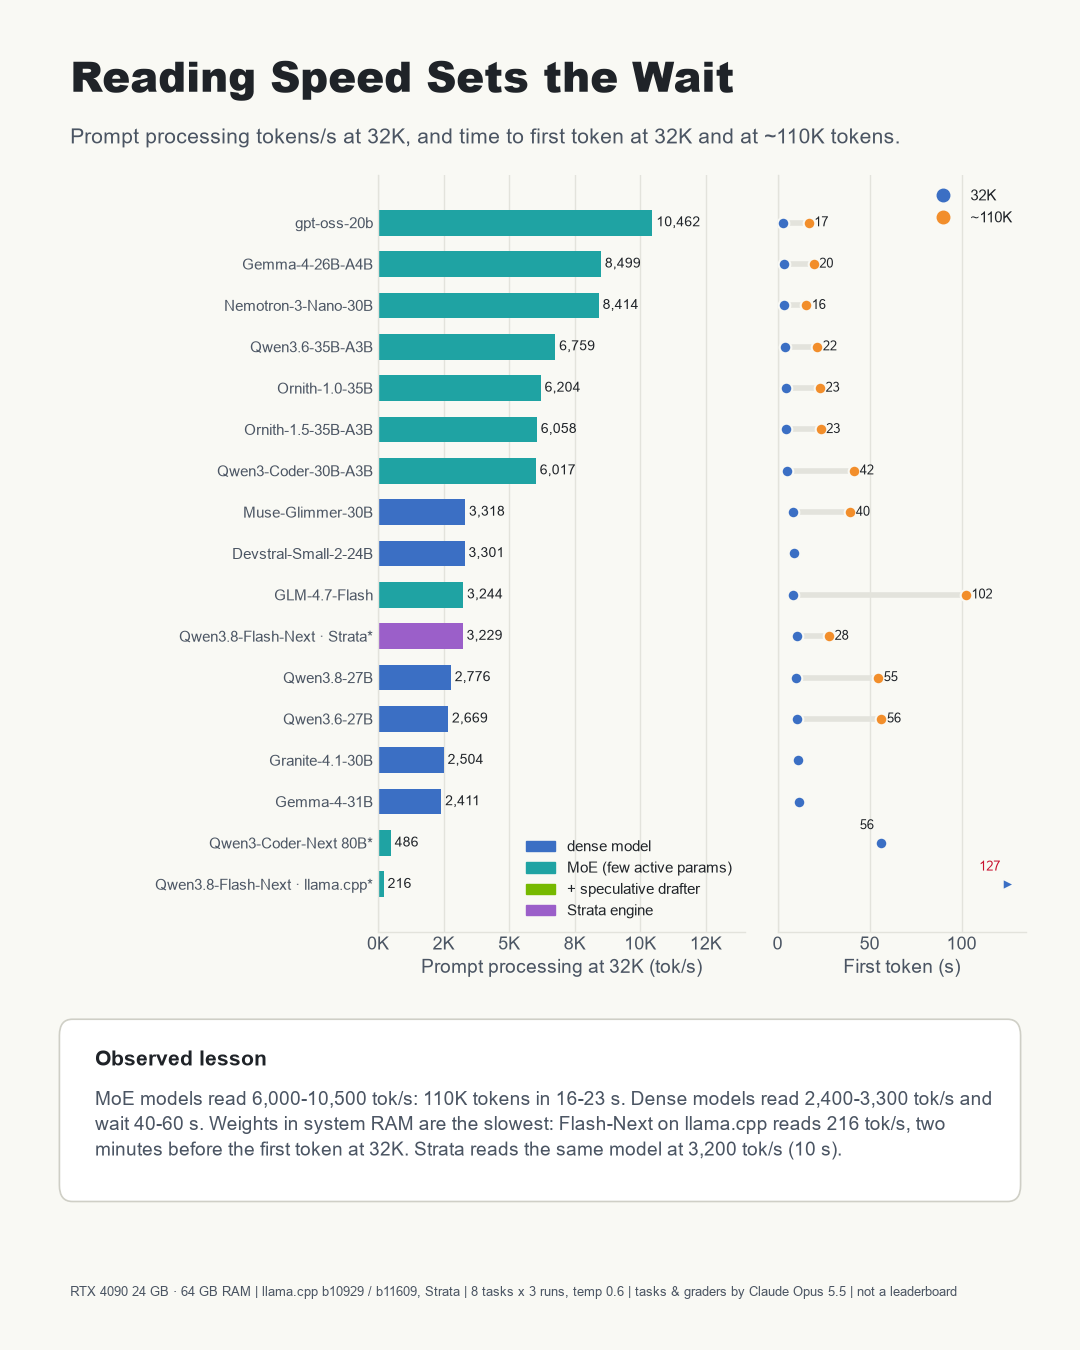
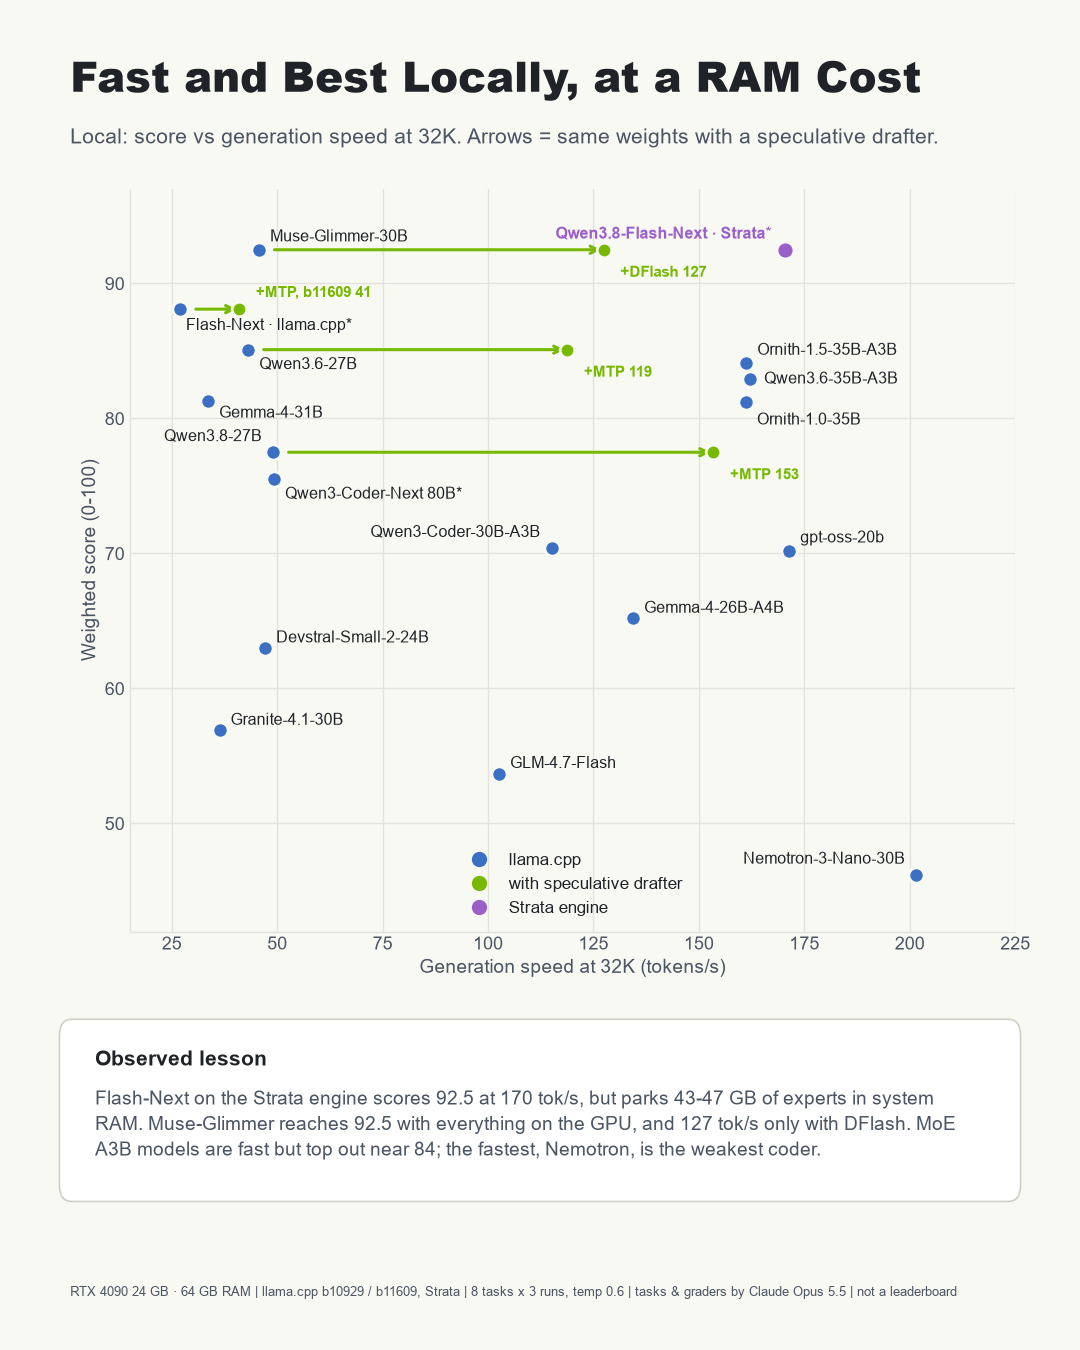
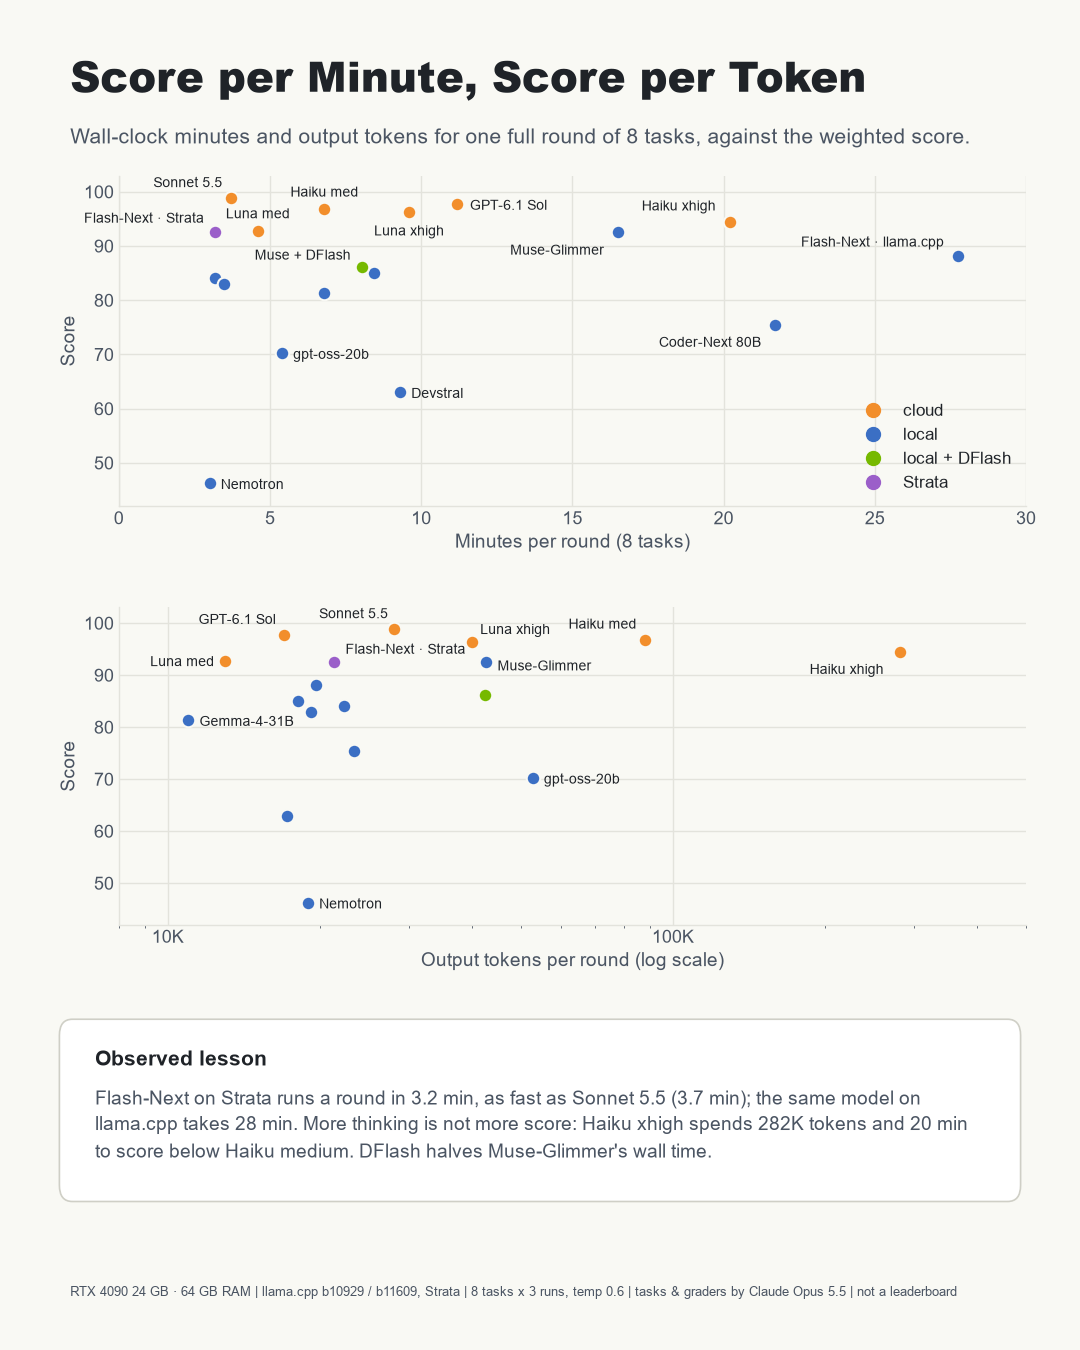
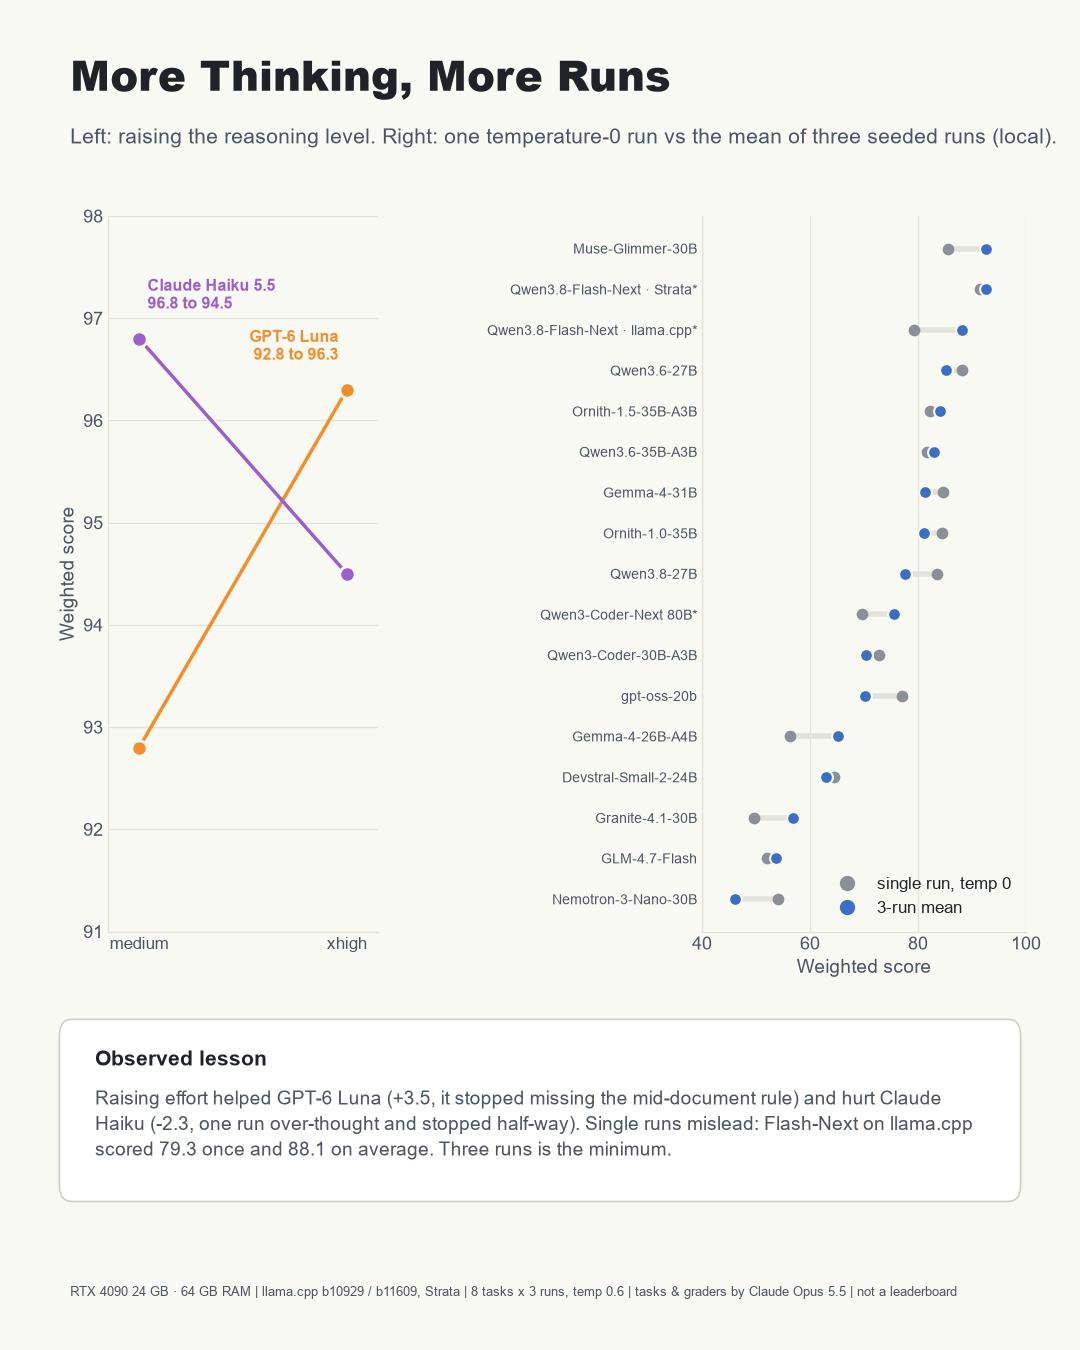
Output speed. Engines, MoE and drafters win.Reading speed. Sets the wait before the first token.Quality vs speed. Fast and best locally, at a RAM cost.Per round. More thinking is not more score.
Engines, builds and sharing
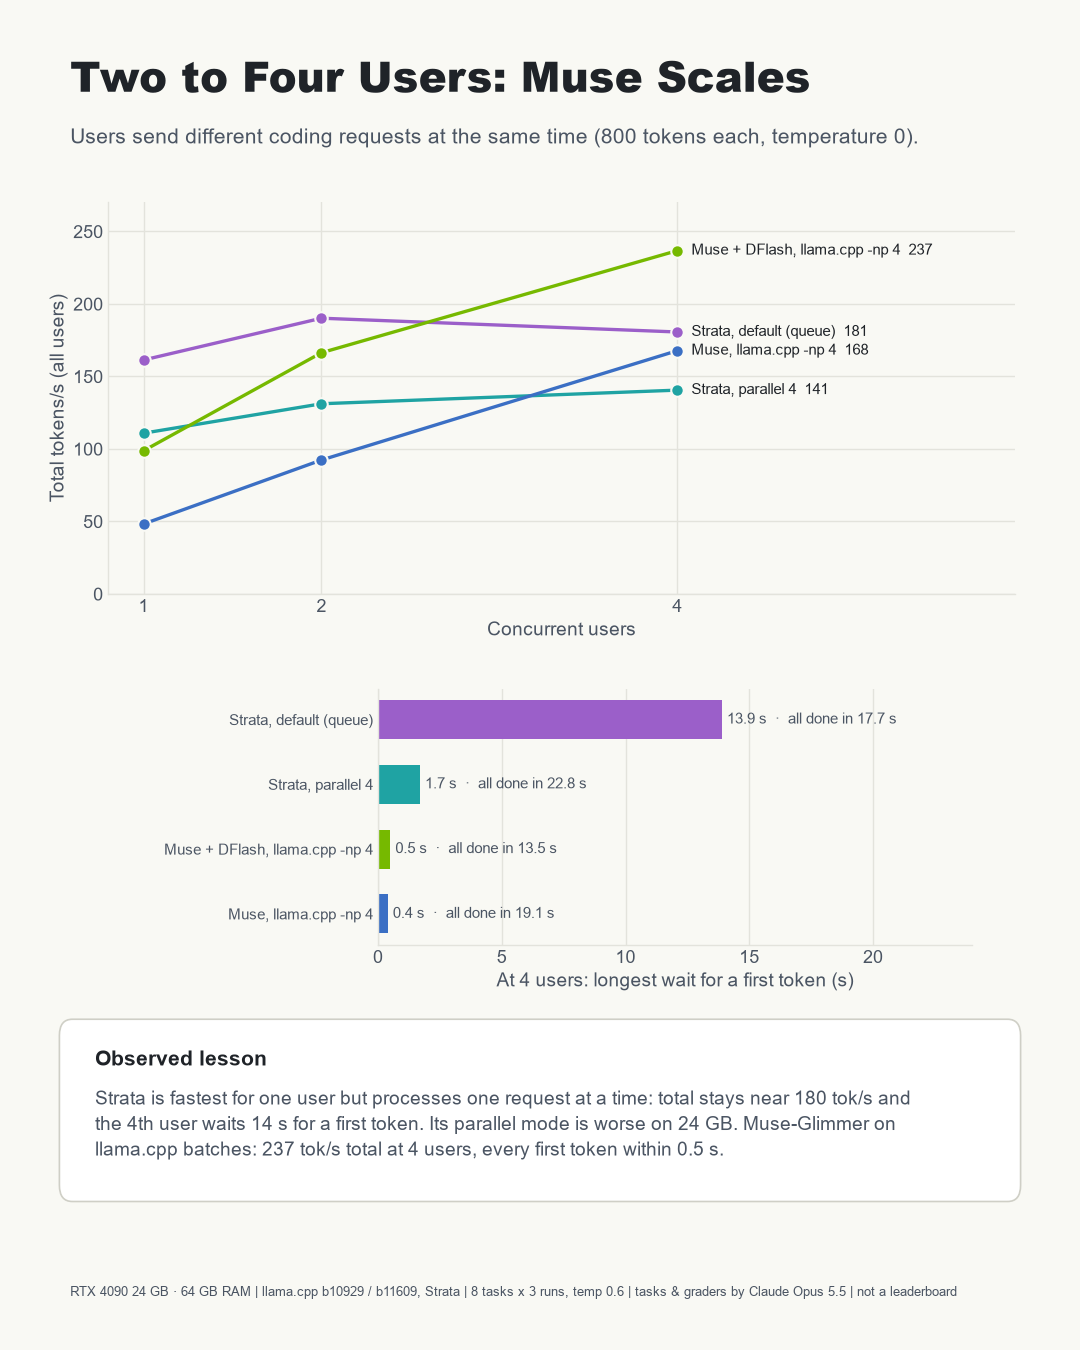
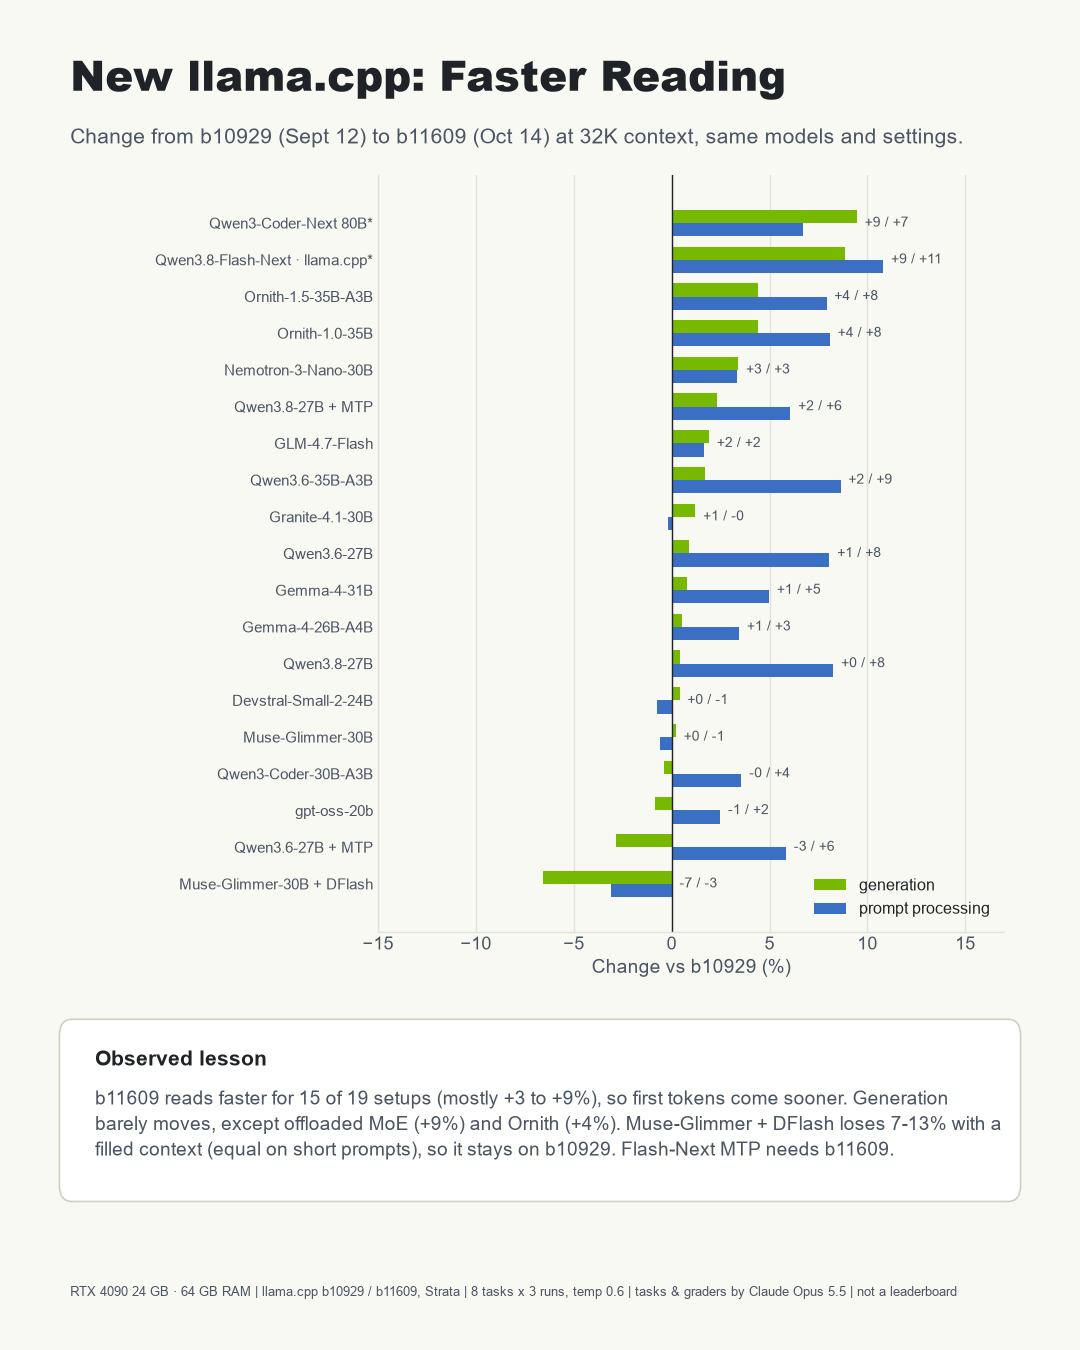
Same model, other engine. Strata is 5.2x faster on the same file.Several users. Muse-Glimmer on llama.cpp scales; Strata queues.New llama.cpp. Faster reading, same writing.
Long context
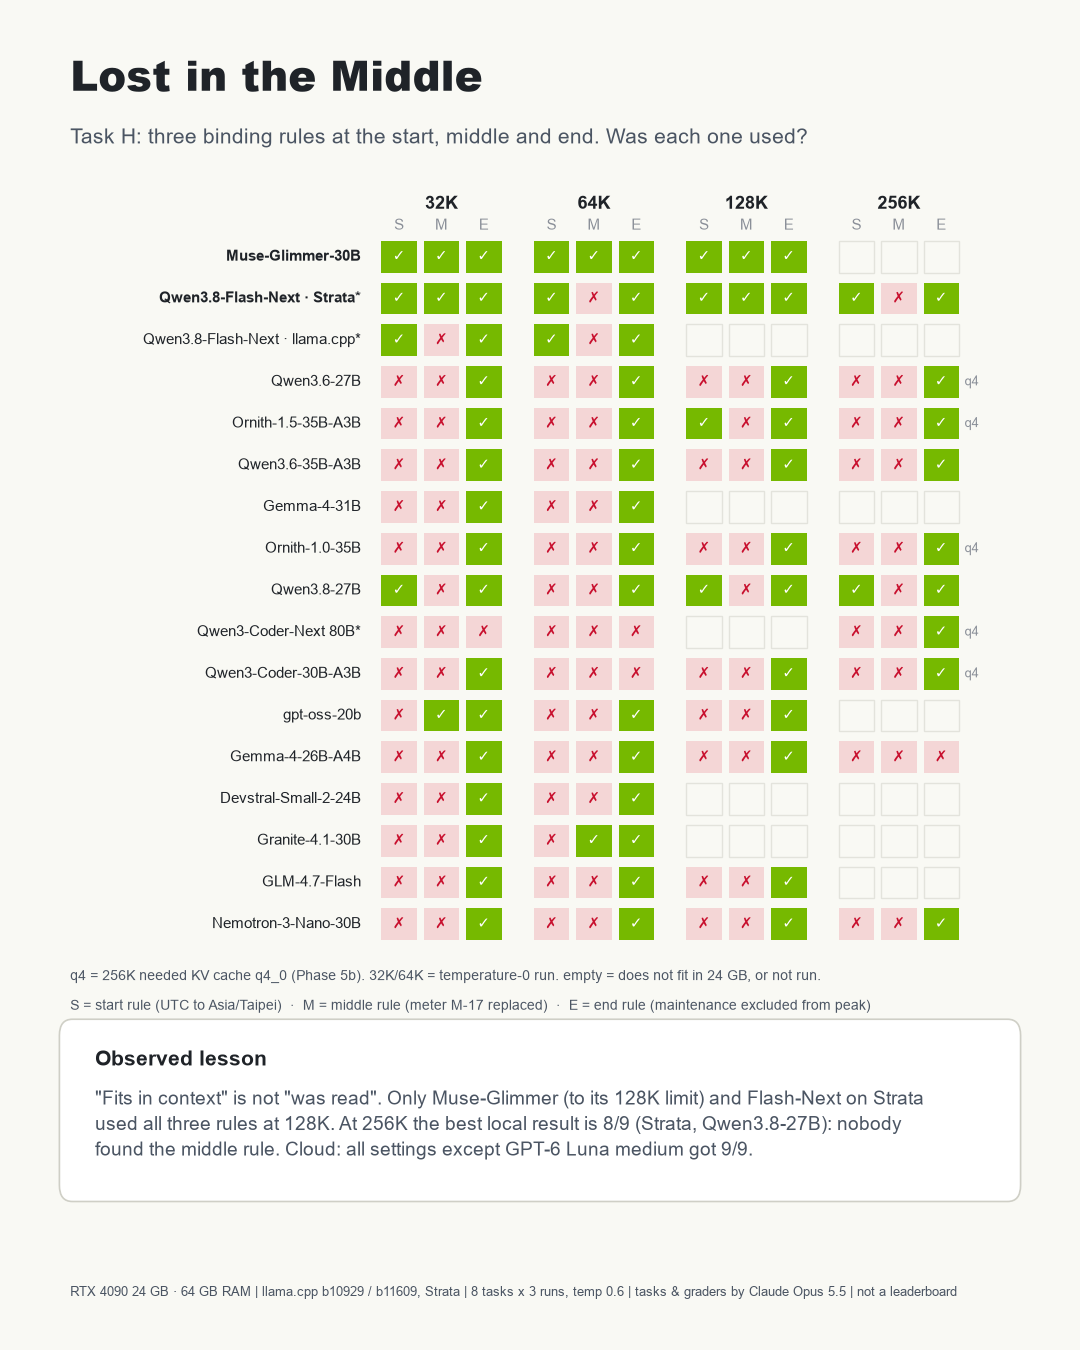
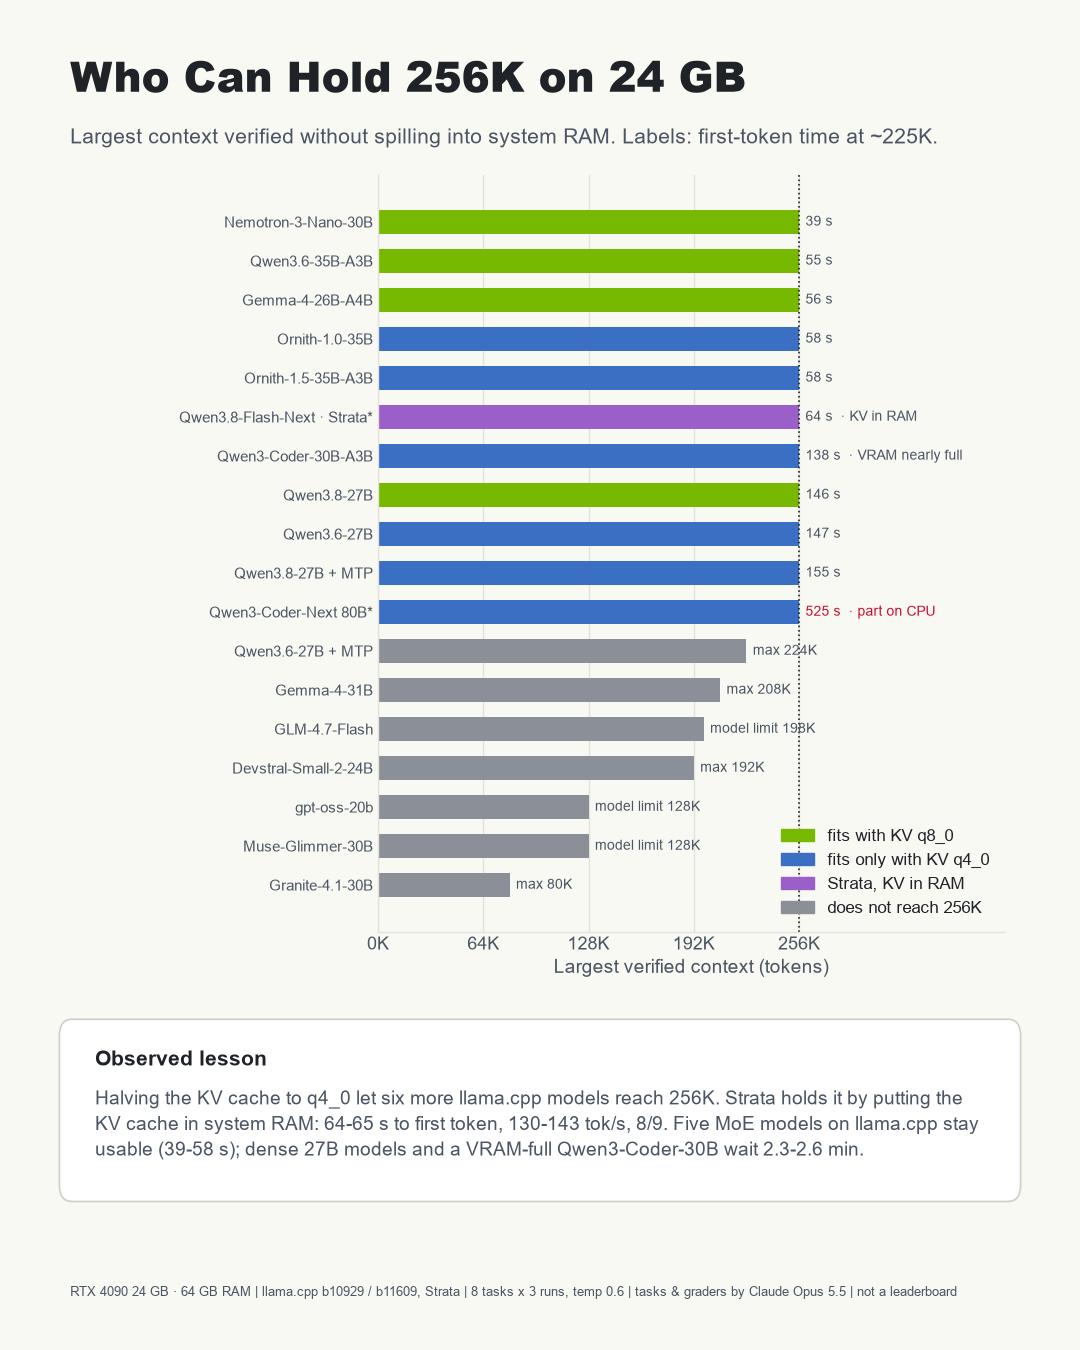
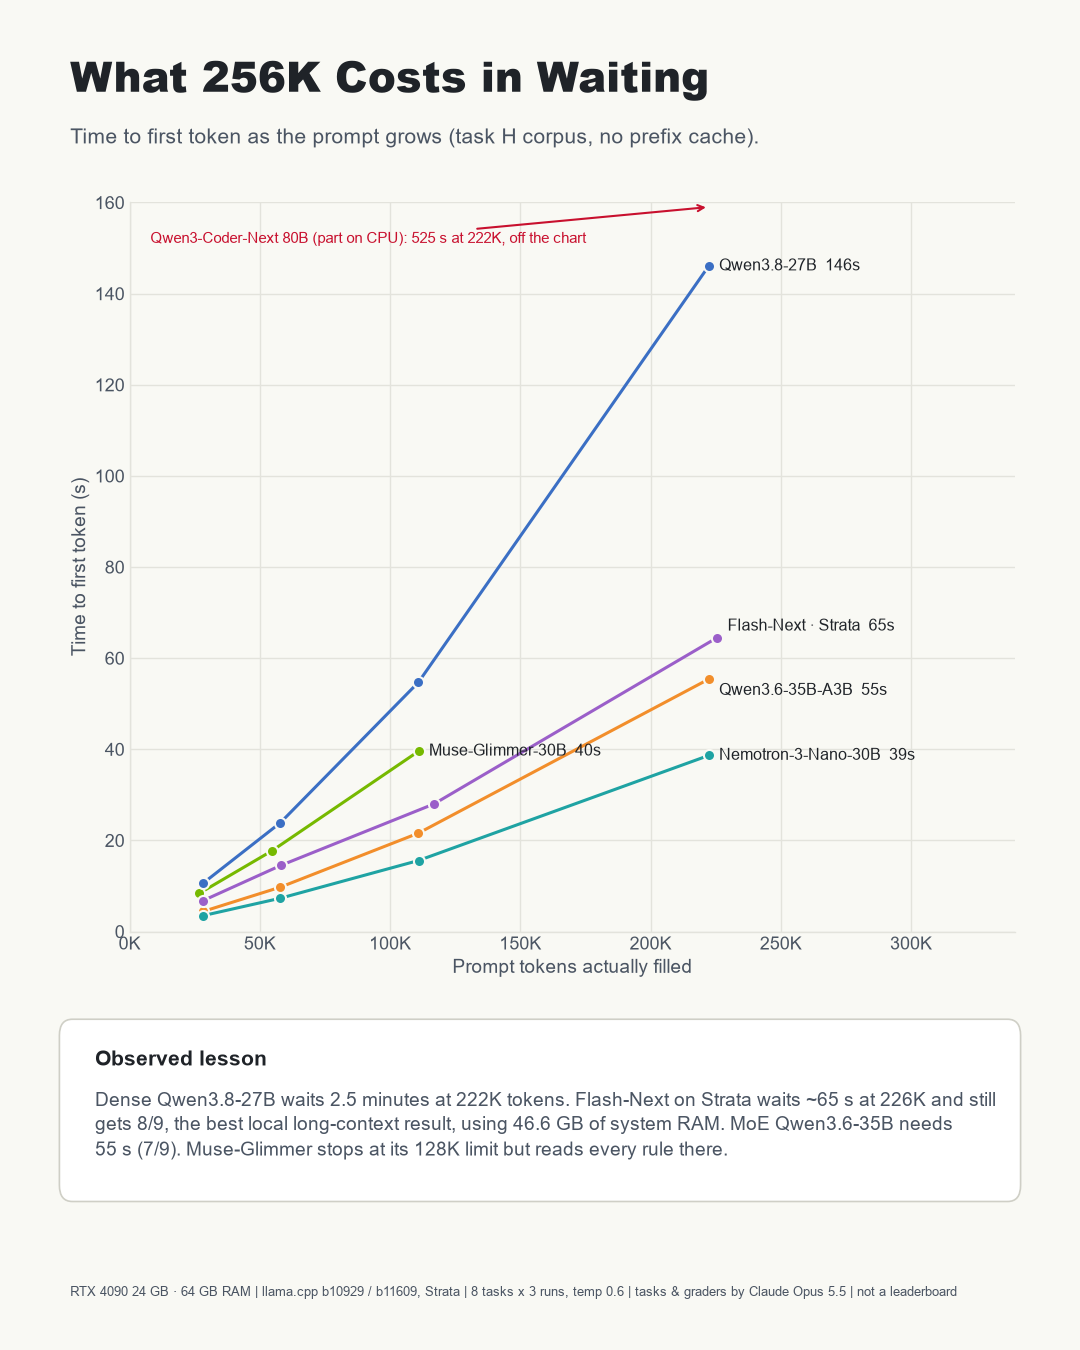
Lost in the middle. At 256K no local setup finds the middle rule.Who holds 256K. Eleven setups, most needing KV q4_0 or system RAM.The wait. 146 s to first token for a dense 27B at 222K.
Videos
Silent clips replayed from the measured timings. Code shown in the typing and multi-user clips is illustrative; every timing is measured.
One round of eight tasks. Cloud and local, 60x time compression.Same function, four speeds. 27 / 46 / 127 / 170 tok/s, real time.Seven steps or forty. Two real agent transcripts.Who answers first at 225K tokens. 10x time compression.Four people, one RTX 4090. Real time.
Method notes
Reasoning level and repeats. Higher effort helped one model and hurt another; single runs mislead.
Claude Opus 5.5 designed the tasks and graders and was not scored. Two contestants are Claude models.
Local output cap was 8,192 tokens including reasoning; cloud CLIs had 32K with continuation.
The two Flash-Next scores used different 3-bit files, so engine and quantisation effects are mixed.
One RTX 4090 with 64 GB RAM, Windows 11, llama.cpp b10929 / b11609 and Strata. Python, SQL and TypeScript/Vue only.